
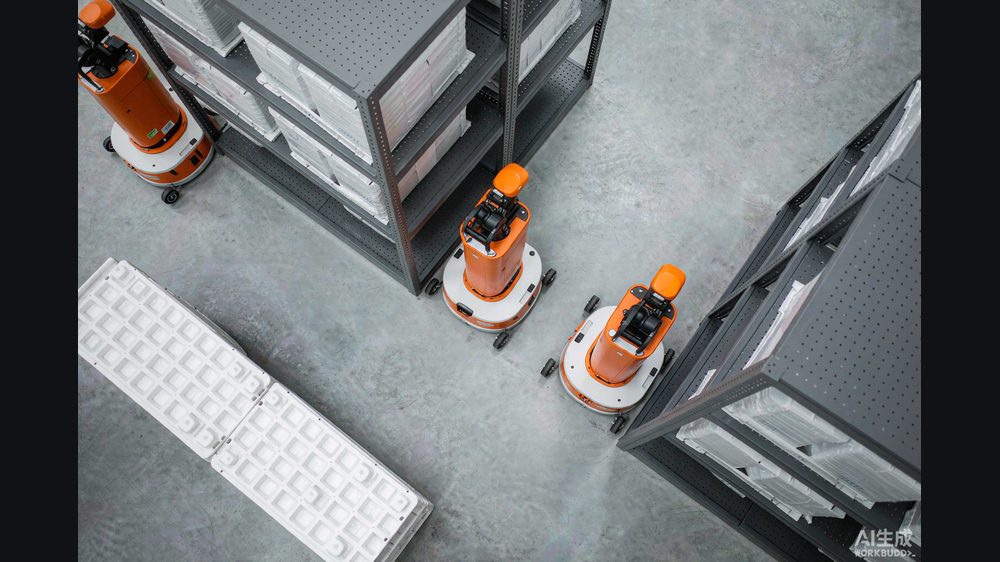
Lightwheel has published details of RoboFinals, a collection of reinforcement-learning environments aimed at long-horizon robot training inside calibrated simulation, with independent evaluation instances and early access availability.
Long-horizon tasks are the current frontier in robot learning. Picking a single object is largely solved in controlled settings; completing a multi-step task - open a drawer, retrieve an item, close it, place it elsewhere - compounds small errors until the policy drifts off distribution.
Simulation lets teams train on that failure mode cheaply, but only if the simulated world matches the real one closely enough. Calibration is the entire product here: sensor noise, friction, latency, and lighting all need to reflect the target hardware.
Independent evaluation instances matter for a different reason. When everyone trains on the same benchmark scenes, reported success rates stop indicating generalisation.
The early-access framing suggests the team is still collecting reference results before publishing comparable leaderboards.